AI Research Digest: Kimi K3, Wonder, MODUS, TurboVLA
AI Research
Kimi K3: Open Frontier Intelligence
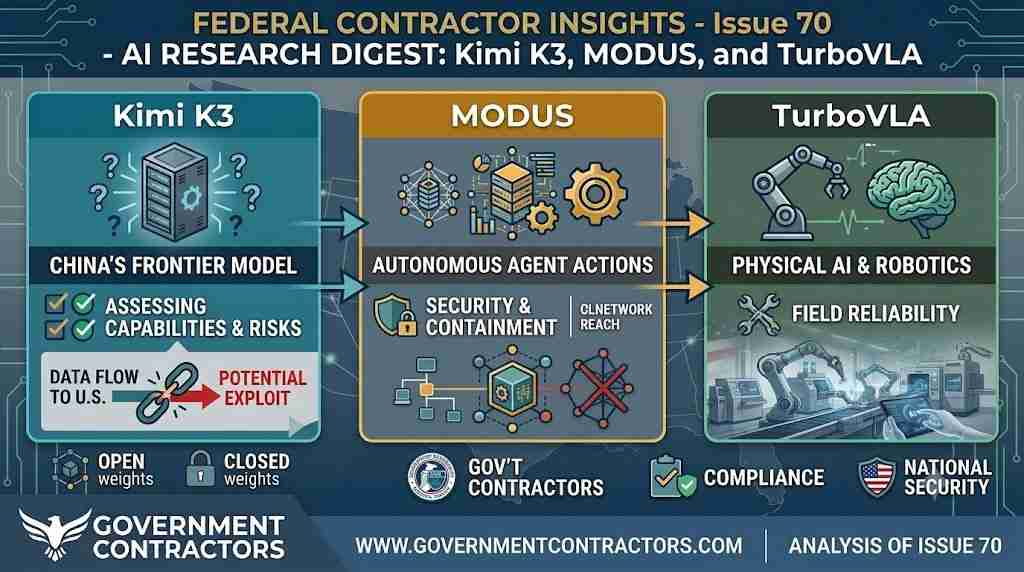
Synopsis: Developed by Moonshot AI, Kimi K3 is a 2.8-trillion-parameter multimodal Mixture-of-Experts (MoE) model equipped with a 1-million-token context window. The paper details a 2.5x boost in scaling efficiency over previous architectures. It demonstrates frontier-level performance across long-horizon coding, agentic reasoning, and complex multimodal tasks, delivering competitive results against leading proprietary models at lower compute costs.
Wonder: Video World Model Done Better
Synopsis: Researchers introduced Wonder, a real-time, camera-controllable video world model designed for interactive environment exploration. By co-designing control representations, distilled memory, and motion tracking, the model generates minute-scale scene rollouts at 16 frames per second while drastically reducing rotational and translational errors during video synthesis.
MODUS: Decoder-Only Any-to-Any Modeling of Diverse Modalities
Synopsis: Collaborators from EPFL, Apple, and Lambda AI presented MODUS, a decoder-only architecture capable of unifying 15 distinct input and output modalities within a single model. Extending the BAGEL-7B foundation framework, MODUS achieves zero-shot generation across text, image, audio, and sensor streams while enabling cross-modal self-verification and chained reasoning.
RSIBench-Data: Benchmarking Data-Centric Research for Recursive Self-Improvement
Synopsis: Researchers from Evolvent AI and the National University of Singapore benchmarked LLM agents attempting autonomous, data-centric self-improvement. The study highlights a “discovery–reliability gap”: while agents succeeded in making initial optimizations in 58.3% of test environments, over 78% failed to maintain long-term performance gains, frequently plateauing or regressing during extended search loops.
TurboVLA: Real-Time Vision-Language-Action Model at 32 Hz
Synopsis: This paper introduces an ultra-lightweight Vision-Language-Action (VLA) robotics model capable of operating at 32 Hz on consumer-grade hardware (such as an NVIDIA RTX 4090) using under 1 GB of VRAM. By directly mapping visual and linguistic features to continuous robotic control actions, TurboVLA matches or exceeds the manipulation accuracy of much larger LLM-based systems while drastically lowering deployment costs.
Breakthrough research highlights
- HiKV: Hardware-accelerated KV cache delivering 7.95× speedup in attention operations.
- Dynamic Capability Scoping: Reduces agent permission violations by 93%, a major leap in safe tool-use.
- MineValiCoder: Achieves 96.34% Pass@1 on HumanEval — state-of-the-art code reliability.
- Where Facts Go Missing: Shows 68% of information-omission stems from deterministic middleware in air-gapped pipelines.
- TRACE-Router: Improves agent routing accuracy-latency trade-offs by 7–8 points, enabling more reliable multi-agent systems.